Shopify to Payload, on Cloudflare Workers
Importing a Shopify catalogue into Payload CMS running on D1 and R2 — why the export CSV isn't a table, and why the batch size is five.
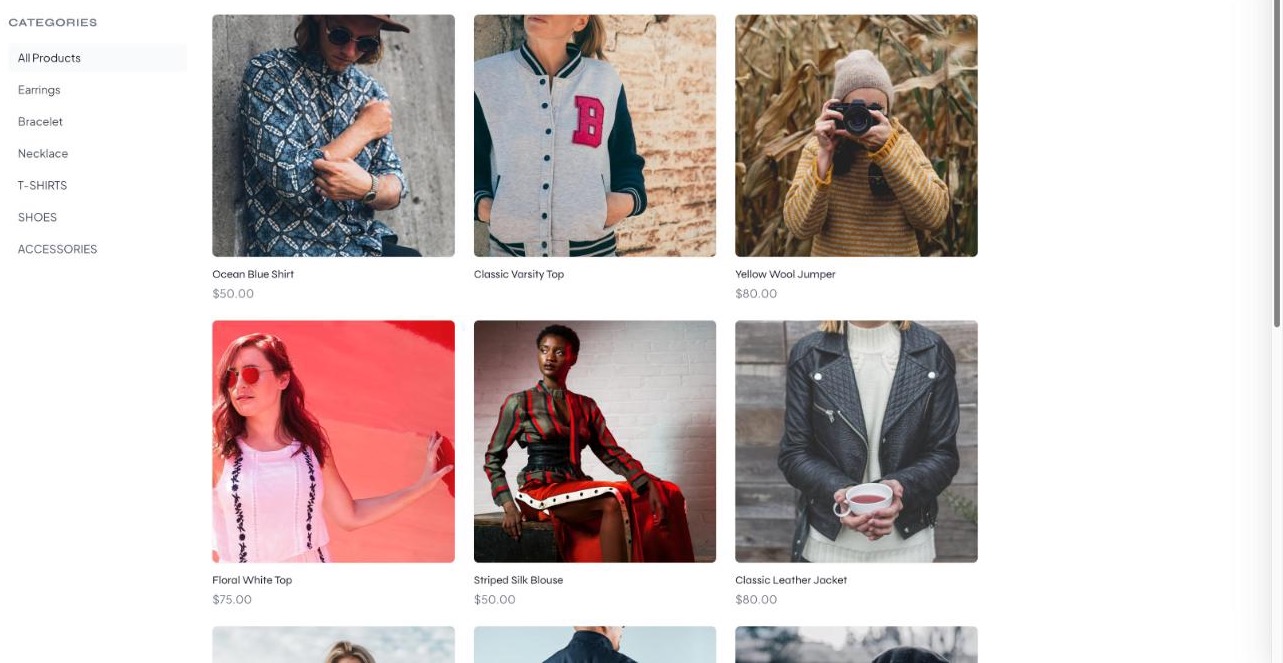
I built a storefront that takes a Shopify catalogue and puts it into Payload, running entirely on Cloudflare. It’s live at shopify2payload.rba.dev.
The stack: Payload 3.85 and Next.js 15 deployed to Workers through OpenNext, D1 for the
database via @payloadcms/db-d1-sqlite, R2 for media, @payloadcms/plugin-ecommerce for
products, variants, orders and payments. Stripe for checkout.
Two things turned out to be more interesting than the framework choices: Shopify’s export format is not what it looks like, and Workers is not Node. Almost every design decision in the importer traces back to one of those.
This is a different project from the legacy-CMS migration I wrote about last year — that one was a multi-brand storefront running two CMSes at once. This one is a single catalogue, moved in one direction, with the importer as the interesting part.
Shopify’s CSV is not a spreadsheet
Export products from Shopify Admin and you get a CSV. It looks like a table where each row is a product. It is not.
One product spans several rows sharing a Handle. The first row carries the
product-level fields — title, body HTML, vendor, tags, SEO — plus the first variant and the
first image. Subsequent rows add more variants, more images, or both. Some rows are
image-only: a Handle, an Image Src, an Image Position, and nothing else.
And the option axis names — Size, Colour — appear only on the product’s first row, while the option values appear on every variant row.
So the first thing the importer does is stop treating rows as records:
// Group rows by handle, preserving file order.
const groups = new Map<string, Record<string, string>[]>()
for (const row of rows) {
  const handle = get(row, 'Handle')
  if (!handle) continue
  const group = groups.get(handle)
  if (group) group.push(row)
  else groups.set(handle, [row])
}
Then, within a group, it has to work out which rows are variants. There is no column that says so. The heuristic:
// Variant rows are the ones that carry a price or an option value.
const variantRows = group.filter(
  r => get(r, 'Variant Price') !== '' || get(r, 'Option1 Value') !== ''
)
That’s a guess, and I’ve written it down as a guess rather than dressing it up. It holds for every export I’ve fed it. It will presumably meet a file where it doesn’t, and when it does I’d rather find a comment admitting the rule than a line of code implying certainty.
The base row gets the same treatment — the first row with a title, not simply the first row:
const base = group.find(r => get(r, 'Title') !== '') ?? group[0]Rows that don’t fit are issues, not exceptions
A catalogue export always has some rows that can’t be turned into a product. A handle with no title anywhere in its group. A group with no variant row.
The tempting thing is to throw. The useful thing is to collect:
export interface MappedProducts {
  products: ShopifyProduct[]
  issues: ProductCsvIssue[]
}
if (!title) {
issues.push({ handle, message: 'No row with a Title — skipped' })
continue
}An import of a few thousand products that dies on row 1,800 tells you one thing. An import that lands 1,799 products and hands back a list of what it couldn’t place tells you everything, and lets you fix the source file once instead of discovering the next problem on the next run.
Nothing gets dropped silently
Shopify has fields Payload’s product collection has no home for. Vendor and Tags are the
obvious ones.
Deleting them during an import is the kind of decision that’s invisible until someone asks where the vendor went, six weeks later. So they survive as metafields:
// Keep source fields we have no dedicated column for (never lossy).
const metafields: ShopifyProduct['metafields']['nodes'] = []
if (vendor) {
  metafields.push({ namespace: 'shopify', key: 'vendor', value: vendor, ... })
}
Ugly, and correct. A migration that loses data quietly is worse than one that carries some awkward baggage across.
Why the batch size is five
Here’s where the platform starts dictating architecture.
export const PRODUCTS_BATCH_LIMIT = 5
export const CUSTOMERS_BATCH_LIMIT = 100
export const ORDERS_BATCH_LIMIT = 25
export const INVENTORY_BATCH_LIMIT = 100
Five products per request. A hundred customers. The difference is images.
Importing a product means downloading its images from Shopify’s CDN and streaming them into R2. A Worker request has an execution budget, and a product with six images is six HTTP round trips before a single database write. Customers are rows of text — a hundred of them is cheaper than five products.
So the CSV is parsed in the browser, in the admin panel, and sent to the server in small batches:
/**
 * REST endpoints backing the admin "Import from Shopify" setup view.
 * The browser parses the CSV, maps it, and sends small batches here —
 * small so each request (image downloads included) stays comfortably
 * within Cloudflare Workers limits.
 */
That’s a genuine inversion of the obvious design. Uploading a 40MB CSV and letting the server work through it is what I’d write on any other platform. On Workers, the upload alone is a problem, and the parse is free on the client anyway. The parser has no dependencies specifically so it can run in both places.
For exports too large even for that, the same mappers and importers are wrapped in a CLI:
pnpm payload run src/migrate/import-csv.ts products products.csvTwo front doors, one pipeline. The admin UI is for the normal case; the CLI is for the case where the normal case won’t fit.
Re-running has to be free
If an import arrives in batches of five, some batch is going to fail — a flaky image URL, a timeout, a closed laptop. The only sane response is to make re-running harmless, so the fix is “run it again” rather than “work out where it stopped and resume from there.”
Every write is find-or-create. Products skip existing slugs. Categories and variant types are looked up before being created. Media is deduplicated by filename:
// Media docs are deduped by filename so shared images (and re-runs) don't
// download or store the same file twice.
async function findOrCreateMedia(payload: Payload, url: string, alt: string) {
  const filename = decodeURIComponent(url.split('/').pop()?.split('?')[0] || '')
  if (filename) {
    const existing = await payload.find({
      collection: 'media',
      where: { filename: { equals: filename } },
      limit: 1,
    })
    if (existing.docs[0]) return existing.docs[0].id as number
  }
  // ...download and create
}
Which also means shared images across products download once, not once per product — the idempotency and the efficiency turn out to be the same property.
There’s a small piece of defensive design I like more than it deserves: products with no image in the source get a generated SVG placeholder, created once and reused, that says “No image in source”. Not a broken image, not a blank card, not a crash. A product that looks exactly as incomplete as it actually is.
D1 migrations are hand-written, deliberately
payload migrate:create doesn’t work in this project. The drizzle snapshots went stale early
and autogeneration now mis-diffs against a baseline that no longer reflects the database. So
schema changes go: add the field, let dev push apply it locally, read the resulting DDL back
out of SQLite, and hand-write the migration from it.
The constraint that shapes those files is that D1 migrations are not atomic. A migration
that fails halfway leaves the completed statements applied. So every one is written to be
walked over twice: IF NOT EXISTS on every CREATE, and all ALTER TABLE ... ADD COLUMN
statements last.
Same principle as the importer, one layer down. Assume it will be interrupted; make the second run a no-op instead of an error.
Workers is not Node, and it tells you late
The failure that cost me the most time had nothing to do with Shopify.
Stripe API calls hung. Not failed — hung, for eighty seconds, then aborted. And only on the
deployed Worker. Locally, under pnpm dev, everything was fine.
The Stripe SDK defaults to a Node http client. On workerd that client doesn’t exist, so
requests go nowhere until the SDK’s own 80-second timeout fires. The fix is one line, applied
in one place:
Stripe.createFetchHttpClient()Webhook signature verification has the same shape of problem for the same reason — Node crypto
isn’t there — and needs constructEventAsync with Stripe.createSubtleCryptoProvider()
instead of the synchronous version.
Every server route now builds its client through a single getStripe() helper, never
new Stripe(...) inline, because this is exactly the class of bug that comes back the moment
someone adds a route and does the obvious thing.
The lesson I actually took from it: pnpm dev runs on Node and the deploy runs on workerd,
and any bug living in that gap is invisible until you deploy. pnpm preview — OpenNext build
plus local wrangler — is the only local command that reproduces it. It’s now the thing I run
before anything involving a third-party SDK.
Would I do it again
Yes, with one caveat.
Payload on D1 and R2 is a genuinely good fit for a catalogue this size, and the ecommerce
plugin meant I extended a product collection rather than designing one. The override pattern —
spread the plugin’s defaultCollection, merge in my fields — kept the variant and inventory
logic I’d otherwise have had to reimplement badly.
The caveat is that “runs on Cloudflare Workers” is a real constraint and not a deployment detail. Bundle size is a limit. Execution time is a limit. Node APIs are absent in ways that surface late and confusingly. Three of the decisions above — client-side parsing, batches of five, hand-written idempotent migrations — exist because of the platform, not because of the data.
That’s a trade I’d make again for what it buys. But it is a trade, and the importer is shaped by it end to end.